


How we take a system from idea to production — and keep it running
Architecture first, iterative delivery, quality gates on every change, and an operating phase that doesn't end at launch.
Great software isn't an accident. It comes from four things, done well every time:
- A sharp outcomeWe agree what success looks like before any code is written.
- Architecture built to lastDesigned for scale, security and change from day one.
- Engineering without shortcutsReviews, tests and quality gates on every change.
- Candid communicationYou hear about risks early, never at the deadline.
Three foundations
Project management that stays out of the way
Every engagement starts by agreeing how we will work together — not by handing you a fixed playbook.
- Communication cadence, channels and a named point of contact on each side, agreed before the first sprint.
- Progress visible in one place, so status is something you can check rather than ask for.
- Risks raised early, when they are cheap to handle — not at the deadline.
- Scope changes handled openly, with their effect on timeline made explicit before they are picked up.
Architecture-driven delivery
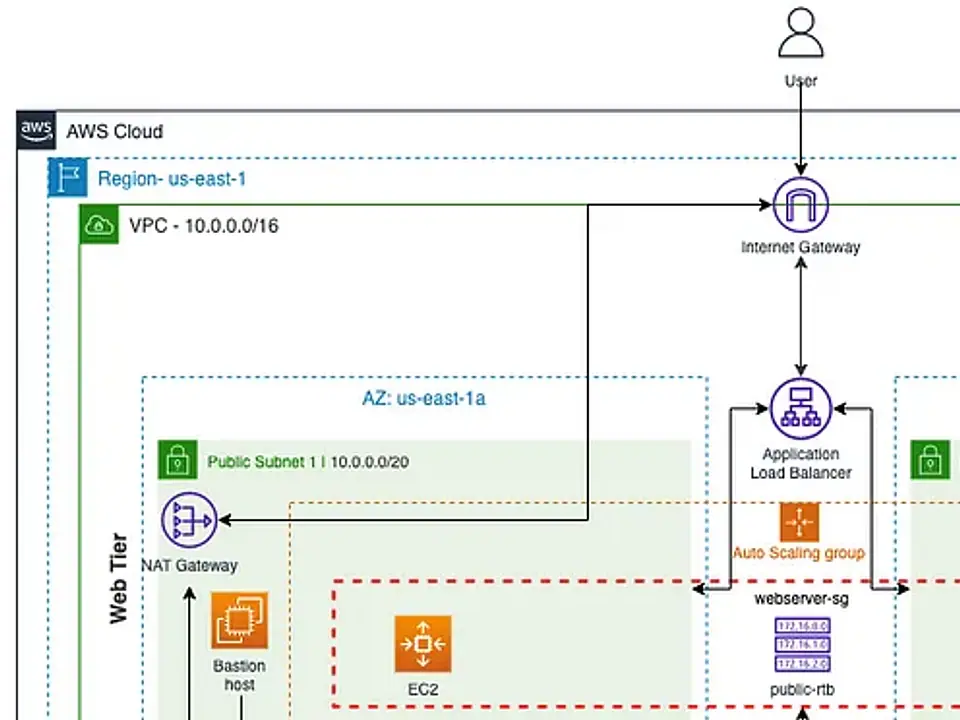
Strong systems start from a deliberate design. We work through four steps before committing to a build.
- Understand the requirements and constraints in detail — what the system must do, and how it must behave (performance, security, cost, operability).
- Design a solution architecture that is ambitious enough to matter and grounded enough to build.
- Document the decisions, trade-offs and interfaces so engineers and stakeholders share one picture.
- Review it before committing: where are the risks, what did we trade away, what changes if a key assumption is wrong.
Engineering discipline
We hold the codebase to a consistent bar on every change, not just at milestones.
- Quality gates on every change: peer review, agreed coding standards, static analysis, and dependency scanning for known-vulnerable packages.
- Tests written alongside the code, so regressions surface immediately rather than in production.
- Technical debt managed on purpose — measured with static analysis and paid down deliberately, not left to compound.
- Knowledge shared: no critical part of the system lives only in one person’s head, so delivery does not stall when someone is away.
The delivery lifecycle
- 01
Discover
We pin down what has to be true for the project to succeed: the business outcome, the constraints (budget, timeline, existing systems, compliance), and the riskiest assumptions. You leave this phase with a prioritized plan, not a ninety-page specification.
- 02
Shape
Analysts and architects turn the concept into a domain model and a set of sized, prioritized requirements, and we design the system architecture around both the functional and non-functional needs. Where a feature is technically uncertain, we build a wireframe or a throwaway prototype to prove it before it enters a sprint.
- 03
Build
Delivery happens in short iterations. Requirements are refined as we go, designs adjust to what testing reveals, and you review working software every sprint — not a single reveal at the end. Feedback from your team is expected and acted on.
- 04
Launch
We get the system production-ready: final testing, documentation, runbooks, and handover or training for the people who will operate it. A staged or beta rollout de-risks the cutover.
- 05
Operate
After release we keep the system healthy: monitoring, incident response, performance and cost tuning, and a backlog of improvements. For AI systems this also means watching model behavior and retrieval quality over time, not just uptime.
Operate: where most partners stop, we continue
Launch is the start of a system's life, not the end of our responsibility. Engagements can roll straight into managed services, with the same engineers, documented runbooks and agreed service levels. For AI systems, Operate includes continuous evaluation of model and retrieval quality, cost and drift.
Governance and communication
We keep governance proportionate to the work. For most engagements that means a small, predictable set of touchpoints rather than a layered review board:
- A weekly delivery sync between your project lead and ours — to plan, re-prioritize, review what shipped, and surface risks.
- A named point of contact on each side for anything that comes up between syncs.
- A working demo and a short review at the end of each phase, covering what is next and any change to timeline or scope.
- A clear escalation path: anything stuck at the team level goes to the delivery lead, then to the founders. We would rather over-communicate a problem early than explain a slip later.
The principles underneath it
Outcomes over output
The goal is the business result, not lines of code or a particular tool. Technology choices follow the problem, not the other way around.
Ownership
The people building your system are accountable for how it behaves in production, not just for closing tickets.
Small teams, clear responsibility
Teams are sized to the work and shaped around the goal, with each person owning a real, nameable part of it.
Feedback as a habit
Frequent, direct feedback in both directions is how quality and trust actually get built over an engagement.
What we add for LLM, RAG and agent work
Generative-AI systems fail in ways generic software delivery does not account for. When the work involves language models, retrieval or agents, we add:
- An evaluation harness with a labeled question set, run in CI, so accuracy changes are caught before release.
- Retrieval and grounding checks, so answers are traceable back to source material.
- Cost and latency budgets set early and monitored — both can grow quietly if nobody is watching.
- Guardrails and observability — input/output filtering, tracing and alerting — in place before anything is put in front of users.
More on this in our AI/ML services and the engineering write-ups on Insights.
What we add for data and workflow automation
- Idempotent tasks and tested recovery paths, so any run can be repeated safely.
- Data contracts and quality checks at every pipeline boundary.
- Deadlines and freshness alerts tied to business outcomes, not just task failures.
- Lineage from source to report or model, so impact analysis takes minutes rather than days.
Ways to work with us
See the engagement-model table on the Services overview.
How this works in practice
Can you work with our existing team and codebase?
Yes. We regularly join an existing team or take ownership of part of a system. Discover includes reviewing what is already there so we are not designing in a vacuum.
How do you handle changing requirements?
Iterative delivery assumes they will change. New or shifted requirements are sized, prioritized against everything else, and their impact on the timeline is made explicit before they are picked up.
How soon do we see working software?
Usually within the first couple of sprints after Shape. You review a working increment every iteration rather than waiting for a single demo at the end.
What happens after launch?
The Operate phase covers monitoring, incident response and ongoing tuning. For AI systems that includes tracking model and retrieval quality over time, not just infrastructure health.
Do you follow a specific certified methodology?
Our approach draws on established agile and software-architecture practice, adapted to each engagement rather than applied by rote. We do not hold formal process certifications; where a project has to work within a specific compliance regime, we align our process to it.
Have a project in mind?
Tell us the outcome you are after and the constraints around it. We will walk you through how the first phase would run.